audio_040896,17:11:35,17:12:35
audio_040896,17:12:35,17:13:35
audio_040896,17:12:50,17:13:50
Paper:
Automated Product Recommendations Without Observable Features: An Initial Investigation'd3
Mary S. Lee and Andrew W. Moore
Question (in academic sense): Can you accurately predict how a consumer will rate a product based historical information? Can you learn about the tastes of given consumer?
Question (in practical sense): Can you tell me whether I should bother watching this weeks Star Trek episode?
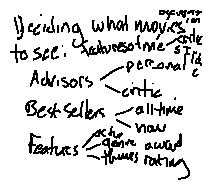
How do you decide whether you want to watch a given episode of Star Trek?
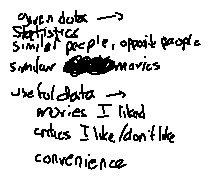
My answers:
Contribution of paper: They attempt to model these three methods into three separate algorithms and then test these algorithms on synthesized data and real data that is both sparse and dense.
Model for their Algorithms:
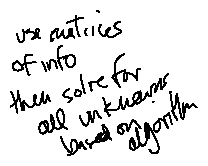
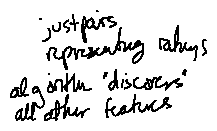
Linfeat Algorithm
Direct approach to prediction by finding the best fit for the two matrices, one of all features and one of all preferences.
Nearest neighbor Algorithm
Indirect approach(inferring). Look for a consumer that has had similar ratings to yours on previous products and uses their rating of current product.
Regression-based Algorithm
Indirect approach(inferring). Look for a strong correlation between your previous ratings and ratings of others.
Traditional Popularity Algorithms:
prodav (NY Times best seller)
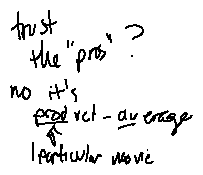
Star Trek Episodes: dense data = 88.8% of maximum entries in polling database of 1055 votes from 36 people on 33 episodes.
Best to worse: (mean error)
Pt: regression offers a 15% improvement over prodval.
Movies: sparse data = 23% of maximum entries in polling database of 4109 ratings from 141 people
and 94 movies.
Best to worse: (mean error)
Pt: Regression offer a 10% improvement over prodval.
Conclusions These algorithms are better at predicting your rating on a particular movie than they are at predicting your taste.